Real sequence, real loss
Six direction clips come from three checked-in 48-frame PyBullet sequences. The loss values change with scene, model, and context.
A frozen world model sees the same simulation forward and backward. Its change in prediction loss becomes a test for the arrow of time.
Reader’s tour ↗Every value below was read from video_000 for the selected scene and context. The footage comes from the matching 48-frame PyBullet sequence.
A re-simulated domino run you can orbit while dragging time in both directions. Forward, the motion spends its energy and goes still. Backward, a settled pile climbs back onto its edges. Hand-authored motion for intuition. It produces no loss values.
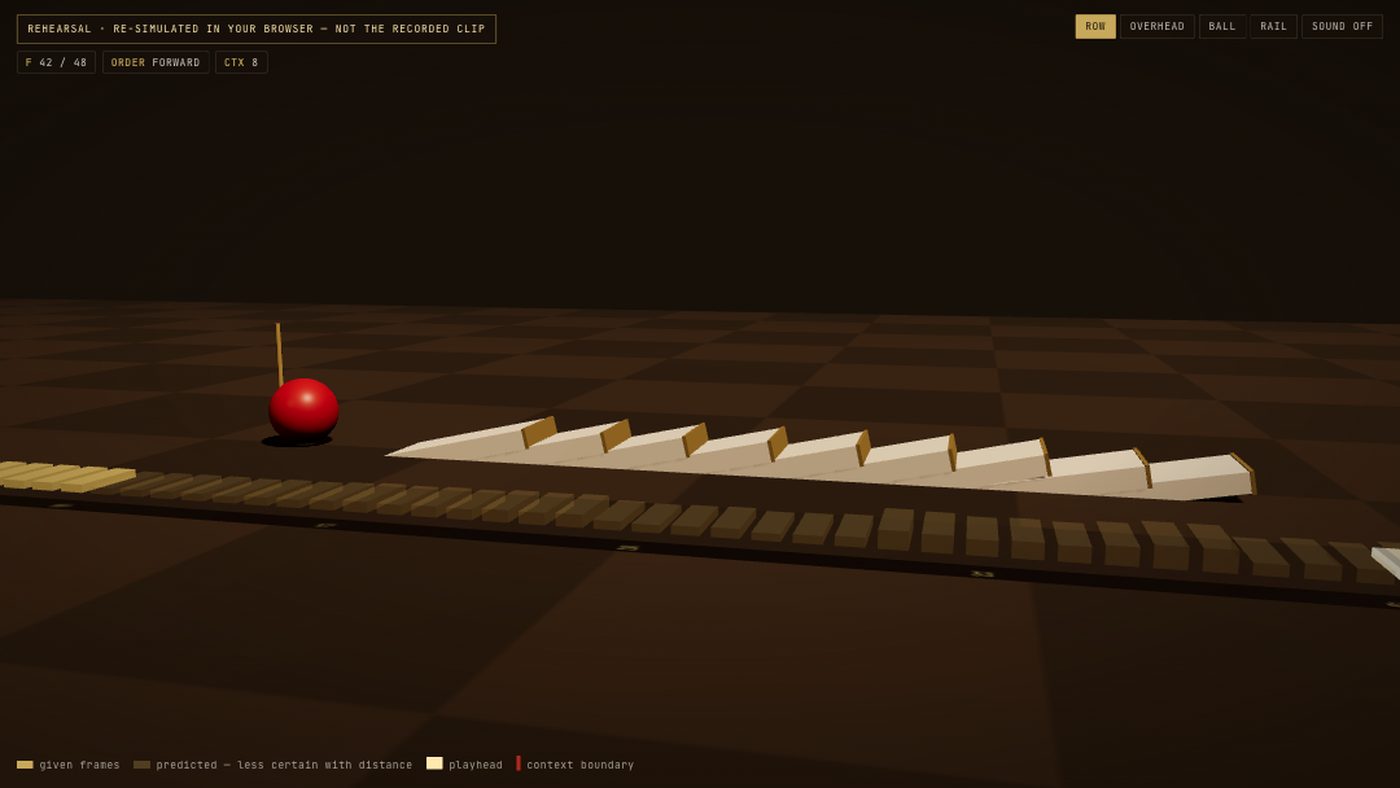
Still image · click to load the world Open on its own page ↗
The interactive lab separates one exact sequence from the paper's aggregate result. It also keeps the post-publication corrections visible.
Six direction clips come from three checked-in 48-frame PyBullet sequences. The loss values change with scene, model, and context.
The paper evaluates 160 discrete-scene videos and 220 continuous restitution or damping videos. A clip is an example, not the claim.
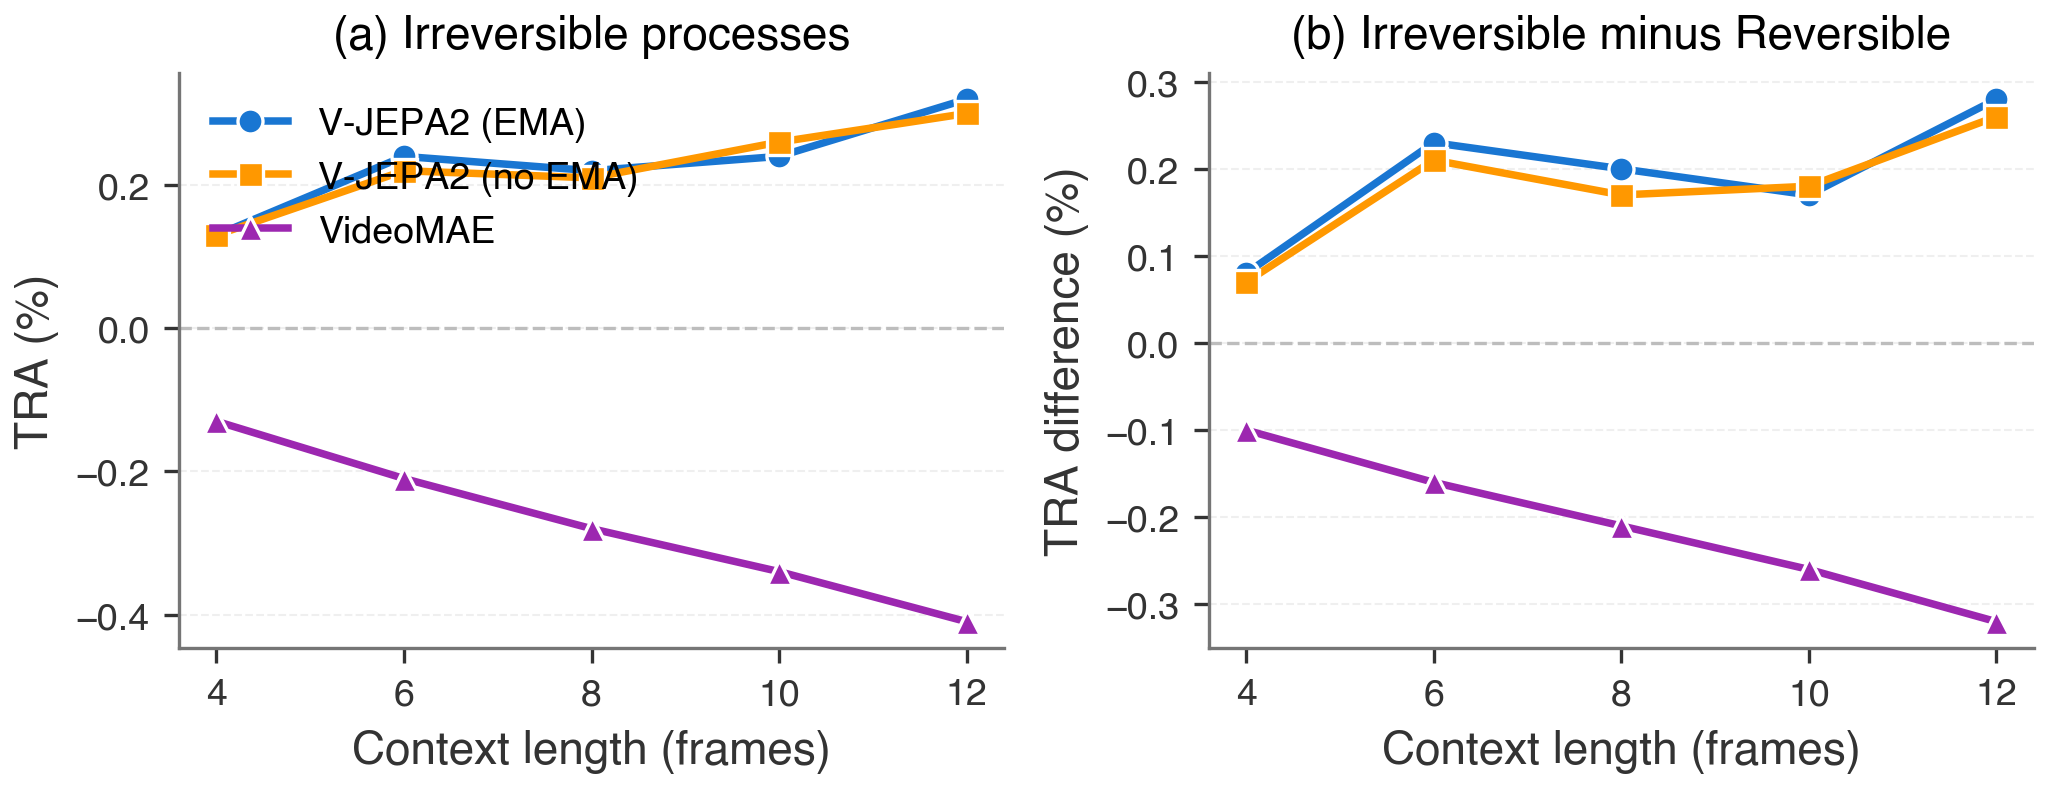
V-JEPA2 shows the expected dissipative separation for contexts 4-12. VideoMAE v1 shows the inverse pattern.
The corrected randomized-domino rerun has no matching frames here, so it appears only in the aggregate evidence. Continuous-sweep videos and per-frame loss traces are also absent.
Positive dissipative separation holds across contexts 4-12 in the corrected randomized-domino rerun. The aggregate sign reverses at context 14.
The inverse pattern survives recomputation. The corrected paper fixes the checkpoint name from VideoMAE v2 to VideoMAE v1.
The public checkpoint had no trained decoder weights. Its result cannot support a claim about distillation.
The evaluator used random-mask inpainting instead of symmetric future prediction. The objective comparison is invalid.
Percentage points. Exact means from the corrected 160-video discrete rerun.
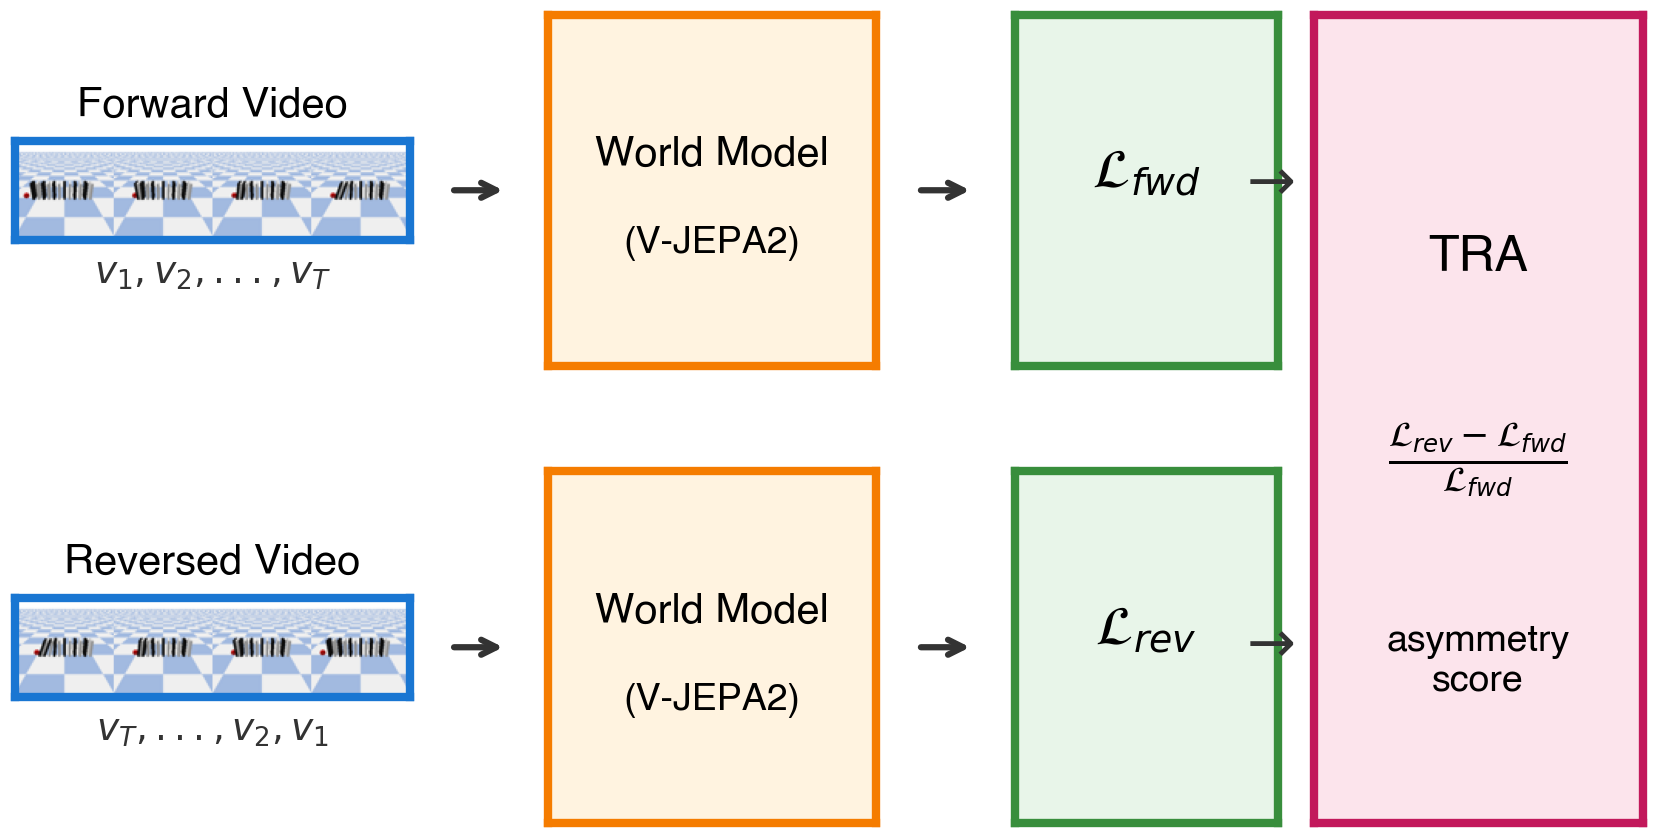
TRA measures a change in prediction loss. It does not prove that a model understands physics. The core evidence is synthetic, and the real-video results remain confounded by human action timing.